Threshold Detection
Where This Document Fits
This document is the second step in the monitor rule configuration workflow. After completing the configuration, return to the main document to continue with step 3: Event Notification.
Data scope: Supports all data types, such as metrics M, logs L, traces T, Real User Monitoring (RUM) data R, objects O, etc.).
Detection Configuration
Detection Frequency
Sets the time interval at which detection is executed.
-
Preset options: 1 minute, 5 minutes, 10 minutes, 15 minutes, 30 minutes, 1 hour
-
Crontab mode: Click “Switch to Crontab mode” to configure a custom interval. Scheduled tasks can be configured to run based on intervals such as seconds, minutes, hours, days, months, and weeks.

Detection Range
Sets the data time range queried for each detection. (❗️The detection range must be greater than or equal to the detection frequency, and it must match the actual data reporting interval to avoid missed detections or false positives.)
- Preset options:
| Detection frequency | Detection range (dropdown options) |
|---|---|
| 30s | 1m/5m/15m/30m/1h/3h |
| 1m | 1m/5m/15m/30m/1h/3h |
| 5m | 5m/15m/30m/1h/3h |
| 15m | 15m/30m/1h/3h/6h |
| 30m | 30m/1h/3h/6h |
| 1h | 1h/3h/6h/12h/24h |
| 6h | 6h/12h/24h |
| 12h | 12h/24h |
| 24h | 24h |
- Custom format: Enter a custom detection range, e.g., 20m (last 20 minutes), 2h (last 2 hours), 1d (last 1 day).
Detection Metrics
Defines the detection data source and aggregation method based on DQL.
Avoid selecting high-cardinality fields as detection dimensions. If configured improperly, the trigger conditions become too loose and may cause frequent alerts. The maximum number of records returned by the current query is 100,000.
Configuration example: When configuring the detection metrics of a monitor, by trace_id was selected as the grouping field.
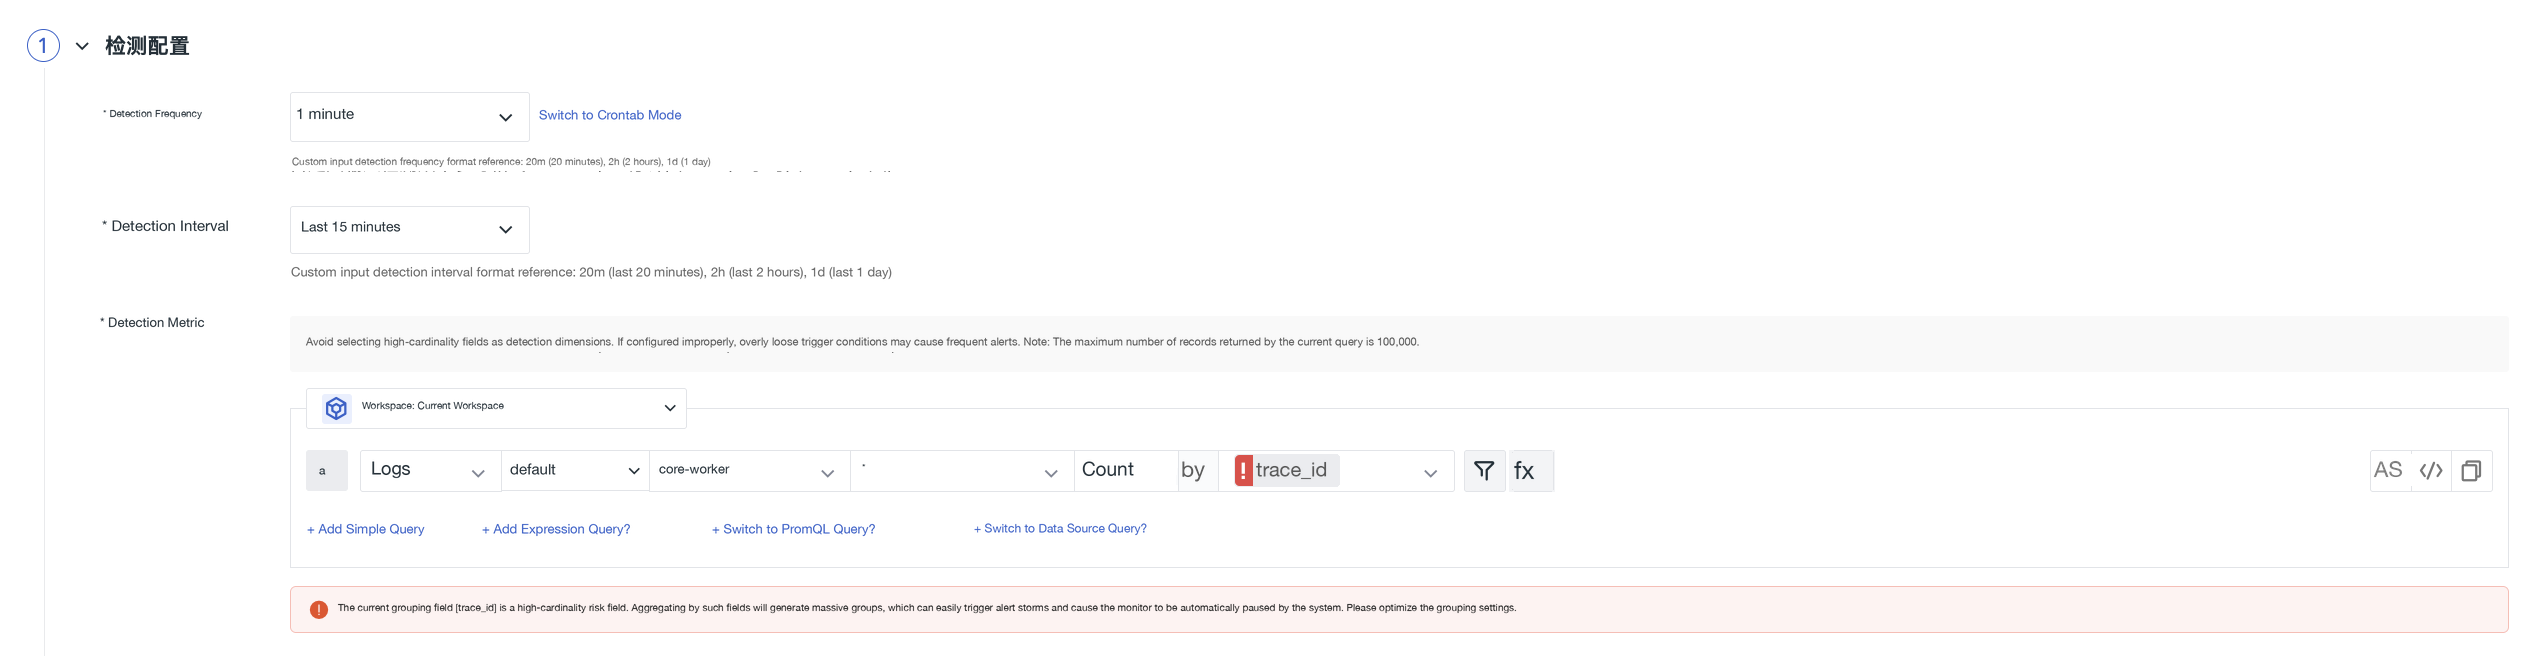
The system then prompts you:
“The current grouping field trace_id is a high-cardinality risk field. Aggregating with such a field generates a massive number of groups, which can easily cause an alert explosion and result in the monitor being automatically paused by the system. Please optimize the grouping settings.”
Configuration Fields
| Configuration item | Description |
|---|---|
| Workspace | Defaults to the current workspace; you can switch to another authorized workspace. After authorization, you can use detection metrics from other workspaces under the current account to create monitors. Once the rule is created, cross-workspace alert configuration is available. Note that when you select another workspace, the detection metrics dropdown only shows the data types that have been authorized for use in the current workspace |
| Data source type | Metrics, logs, traces, RUM, etc. |
| Query method | Simple query, expression query, PromQL query, data source query |
| Filter conditions | Filter detection targets by tags |
| Aggregation method | avg, sum, max, min, count, etc. |
| Function support | Click the fx button to choose from the following functions:❗️When selecting the conversion functions derivative, difference, non_negative_derivative, or non_negative_difference, you need to add an interval. For example: [::5m] |
Click to view query method details and more information on function usage.
Trigger Conditions
Configure trigger conditions and severity levels. When the query returns multiple values, an event is generated if any value satisfies the trigger condition.
Supports four severity thresholds—Critical, Error, Warning, Notice—as well as a Normal recovery condition.
| Level | Configuration | Description |
|---|---|---|
| Critical | When Result >= [value] |
Highest severity alert; requires immediate handling |
| Error | When Result >= [value] |
High severity alert; requires priority handling |
| Warning | When Result >= [value] |
Medium severity alert; requires attention |
| Notice | When Result >= [value] |
Low severity alert; requires monitoring |
| Normal | No event generated after [N] detections |
If the detection metric triggers a Critical, Error, Warning, or Notice anomaly event, and the next N consecutive detections are all normal, a Normal event is generated. Used to determine whether the anomaly has recovered. Recommended |
For more details, see event level description.
Advanced Options
Consecutive Trigger Evaluation
When enabled, events are generated only when the trigger condition is continuously satisfied, avoiding false positives caused by momentary fluctuations (❗️The maximum configurable limit is 10).
Bulk Alert Protection
Enabled by default.
When the number of alerts generated by a single detection exceeds the preset threshold, the system automatically switches to a status-based summary strategy: instead of handling each alert object individually, it generates and pushes a small number of summary alerts based on event status.
This ensures timely notifications while significantly reducing alert noise and avoiding the risk of timeouts caused by processing too many alerts.
When this toggle is enabled, such event details generated after subsequent monitor detection of anomalies will not display history records or related events.
Recovery Conditions
Configure recovery conditions and severity levels. When the query returns multiple values, a recovery event is generated if any value satisfies the trigger condition.
Set independent recovery thresholds for different levels to implement graded recovery. For example, an Error alert recovers only when the value drops below 70, while a Warning alert can recover when the value drops below 80.
Recovery Alert Logic
Once the recovery condition is enabled, the system uses the Fault ID as the unique identifier to manage the entire alert lifecycle (including operations such as creating Issues).
When the graded recovery feature is also enabled:
-
The platform configures a separate set of recovery rules (i.e., recovery thresholds) for each alert level (such as
critical,warning) -
The alert status and recovery status of each level are calculated independently
-
The alert lifecycle identified by the original Fault ID is not affected
Therefore, when a monitor triggers an alert for the first time (i.e., starts a new alert lifecycle), the system generates two alert messages simultaneously. They appear identical because:
-
The first alert source: the overall check (
check), which represents the start of the entire incident lifecycle (based on the original rule); -
The second alert source: the graded detection (
critical/error/warning/…), which indicates that the enabled graded recovery feature has been activated, used to present the specific alert level and its subsequent recovery status (such ascritical_ok).
In the above, the df_monitor_checker_sub field is the core basis for distinguishing the two types of alerts:
-
check: indicates the result of the overall check; -
Other values (such as
critical,error,warning, etc.): correspond to the results of the graded detection rules.
Therefore, when an alert is first triggered, two records appear with similar content but different sources and purposes.
df_monitor_checker_sub |
T+0 | T+1 | T+2 | T+3 |
|---|---|---|---|---|
check |
check |
error |
warning |
ok |
critical |
critical |
critical_ok |
||
error |
error |
error_ok |
||
warning |
warning |
warning_ok |
Data Gap
Handling strategy when the detection metric returns no results within the detection range:
| Option | Description |
|---|---|
| Do not trigger events (default) | No alert is generated when there is no data; suitable for scenarios where data gaps are acceptable |
| Treat query result as 0 | Treat empty data as a value of 0 for threshold evaluation |
| Trigger data gap event | Treat no data as an anomaly and trigger a data gap event |
| Trigger Critical event | Trigger a Critical event when there is no data |
| Trigger Error event | Trigger an Error event when there is no data |
| Trigger Warning event | Trigger a Warning event when there is no data |
| Trigger Notice event | Trigger a Notice event when there is no data |
| Trigger recovery event | Trigger a recovery event when there is no data |
When trigger conditions, data gap handling, and info generation are configured together, triggers are evaluated in the following priority: Data gap > Trigger conditions > Info event generation.
That is: first determine whether data is missing, then determine whether a threshold is triggered, and finally determine whether an info event is generated.
Info Generation
After enabling this option, you need to configure the info generation condition. The system writes an Info event only when the detection result does not trigger any of the Critical, Error, Warning, or Notice thresholds and the info generation condition is satisfied.
Suitable for scenarios that require recording normal status changes or low-priority information.
Next Steps
After completing the detection configuration above, continue with:
-
Event Notification: define the event title, content, notification members, data gap handling, and related incidents;
-
Alert Configuration: select an alert policy and set notification targets and mute periods;
-
Link: associate a dashboard for quick navigation to view data;
-
Permissions: set operation permissions to control who can edit or delete this monitor.